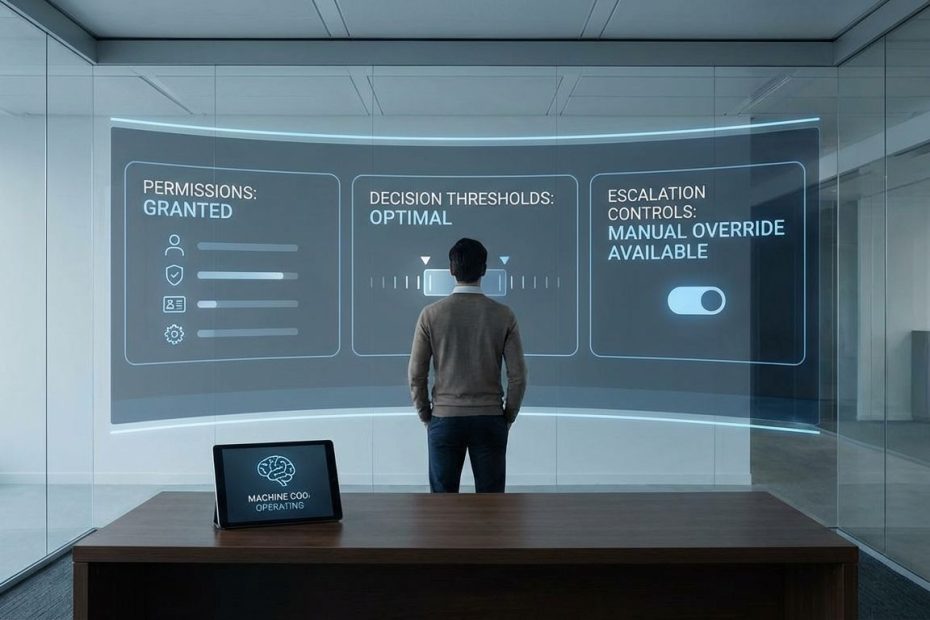
You can manage a “machine COO” by treating it like a production operator with delegated authority, enforced controls, measurable service levels, and a human escalation chain, not like a chatbot you “prompt better.” The winners assign decision rights, constrain access, instrument every action, and hold leaders accountable for outcomes the system influences.
This article shows how to run machine leadership without theater: where algorithmic operations already work, why so many agentic pilots stall, how to prevent security blowups, how to structure accountability, and how to scale autonomy without losing employee trust. Expect concrete operating moves, crisp guardrails, and execution metrics you can put into an ops review.
Can AI Actually Be A COO, Or Is This Just “Agent Washing”?
AI can perform real COO work when the work is operational, repeatable, and instrumented: routing work, enforcing policy, reconciling records, managing queues, and triggering approvals. That’s “COO function,” not “COO title,” and it matters because most companies don’t need an autonomous executive brain. They need reliable, always-on operations management across systems that humans can’t babysit hour by hour.
The market noise is where teams get hurt. Gartner has warned that many vendors are rebranding assistants, RPA, and chatbots as “agents,” and it predicts over 40% of agentic AI projects will be canceled by the end of 2027 due to escalating costs, unclear value, or inadequate risk controls. That should change how you pitch the work internally: sell narrow authority with hard metrics, not sweeping autonomy with vague benefits.
A machine COO is credible when you state the boundary in plain language: “This system owns these workflows, inside these tools, within these thresholds, under these audit rules.” If that boundary can’t be written down in a single page, the system isn’t a COO. It’s a demo.
What “Machine Leaders” Are Enterprises Using Right Now That Actually Works?
The highest-velocity wins sit in operations hygiene and coordination, where errors are measurable and reversibility is possible. You see success in stewardship agents that keep CRM and ERP data consistent, ticket triage that normalizes requests into standard categories, and dependency chasing that forces owners, dates, and blockers into the open. That’s not glamorous, and it’s exactly why it scales: it’s operational discipline that humans avoid, delivered with consistency.
Teams also get real value from monitoring and exception handling. When the agent watches system health, inbound queues, SLA breach risk, inventory anomalies, or vendor feed failures, it can page humans early with a structured diagnosis. The important move is that the machine doesn’t “manage people” first, it manages operational signals first. Once signals are accurate, human performance conversations get simpler and less political.
This is also where you avoid the pilot trap. Many agent programs stall because they start in high-emotion zones (performance management, compensation, staffing) before the organization has earned trust in the system’s accuracy. Start where the machine can prove it is predictable, then widen authority.
How Do You Manage An AI “Leader” So It Doesn’t Go Rogue Or Create Chaos?
Management starts with identity and access, not prompts. The agent needs a dedicated machine identity, scoped entitlements, and strict separation between read permissions and write permissions. If it can read payroll, it should not automatically gain write access in HRIS, messaging platforms, and finance tooling. Entitlements should map to job role just like a human COO’s delegated authority, with narrower access by default.
Decision rights need a signed, enforceable matrix. Define exactly what the agent can approve, what it can recommend, what it can draft, and what it must escalate. Put numeric thresholds on high-impact actions: refund limits, vendor spend limits, discount ceilings, contract term changes, staffing plan adjustments. If a threshold can’t be expressed numerically or with a finite policy rule, keep it in recommendation mode until the policy exists.
Operational controls need to be rehearsed, not documented. Run a kill switch drill, run rollback drills, and run containment drills where the agent is cut off from tools but retains read access for investigation. If an incident response leader cannot disable the agent in under a minute, the agent is not managed, it’s tolerated.
If An Algorithm Makes The Call, Who Is Accountable Legally And Operationally?
Accountability does not move to the algorithm, it concentrates in the humans who authorize its authority. A machine COO changes the shape of accountability: it becomes less about “who clicked the button” and more about “who approved the policy, thresholds, data sources, and access.” That’s a sharper form of responsibility, and strong operators welcome it because it forces clarity.
Regulators are also moving toward explicit expectations for transparency and human oversight in workplace decision systems. In the EU, the AI Act has a high-risk category that includes recruiting-related use cases and calls for strict requirements including risk management, data quality, clear user information, and human oversight. If the machine COO touches hiring, scheduling, discipline, pay, or termination decisions, governance has to resemble regulated infrastructure, with documented controls and human review paths.
Operationally, the clean way to run this is to name a human “business owner” and a human “system owner.” The business owner owns outcomes and policy, the system owner owns reliability, logs, access, and incident management. When those roles blur, organizations end up with an agent that can act and no one who can answer for it.
Will AI Managers Be Biased, And How Do You Prove They Aren’t?
Bias shows up in outcomes, not intent. Avoiding protected attributes in prompts does not protect you if decisions still create disparate impact due to proxy variables, historical patterns, or skewed labels. If the agent recommends who gets staffed on high-visibility projects, who gets performance scrutiny, or whose timecards get flagged, it can create unequal outcomes even when it never “sees” sensitive fields.
Proof requires an audit posture that looks like operations, not PR. You need pre-deployment testing on representative data, subgroup performance checks, and documented acceptance criteria that leaders sign. Monitoring cannot stop at launch; drift happens when job roles change, when business cycles shift, or when tooling changes break a data feed and silently change feature distributions.
Recourse is part of proof. Employees need an appeal path that produces a human answer and a logged resolution. If the system flags someone for “low performance risk,” the employee must be able to request the inputs that drove the flag and get a human review. Without that, trust collapses, and workarounds spread faster than any governance memo.
What’s The Fastest Way To Pilot An “AI COO” Without Blowing Up Trust?
Speed comes from narrowing scope, then widening authority on evidence. Start with read-only reporting and structured recommendations tied to measurable outcomes: cycle time, backlog age, error rate, cost-to-serve, on-time delivery, and exception volume. Your goal is to prove the machine can describe the business accurately before it starts changing the business.
Move next into constrained action with approval gates. The agent drafts changes, prepares the execution plan, and submits an approval package that includes expected impact, affected systems, rollback steps, and audit logs. Humans approve with one click, and the agent executes exactly what was approved. That preserves speed while keeping control.
Autonomy comes last, and only inside playbooks. Autonomy should mean “the agent can complete end-to-end actions inside a defined runbook and pages humans on exceptions,” not “the agent decides what work matters.” If the runbook can’t be versioned, reviewed, and tested, keep that area out of autonomous scope.
What Are People Worried About When The “Boss” Is An Algorithm?
The operational worry is arbitrariness. Employees can accept strict rules faster than they accept unclear rules. If the machine denies a request, reprioritizes work, or flags risk without stable explanations, the organization gets learned helplessness: people stop planning, stop taking ownership, and start optimizing for what they think the machine wants.
The second worry is invisible surveillance creep. When agents monitor productivity signals, messaging metadata, tickets, commits, or time-in-tool, employees assume the system is judging them even when it’s only managing throughput. If you allow that ambiguity, your rollout creates fear and avoidance behavior, which wrecks data quality and makes the system worse.
Your job is to operationalize transparency. Publish the decision inputs the agent is allowed to use, publish the thresholds, publish the escalation paths, and publish what the system is forbidden to do. If the organization cannot state what the machine COO will never decide, people will assume it decides everything.
How Do You Build A “Machine COO” Operating Model That Scales Past The Pilot?
Scaling requires an operating model with the same rigor used for finance systems and production services. Start with a service catalog: what workflows the agent owns, what tools it can touch, what SLAs it must meet, and what error budgets are acceptable. Treat every workflow as a product with a named owner, a version, and a measured reliability profile.
Instrumentation is non-negotiable. Every tool call, read, write, approval, and exception needs structured logs. Add semantic telemetry that records the intent, the action, the objects touched, and the policy invoked. When a stakeholder asks, “Why did this happen,” you should answer in minutes from logs, not days from interviews.
Then implement change control that respects operations reality. Model upgrades, policy changes, tool connector updates, and permission changes must flow through a single release gate with testing, rollback, and post-release monitoring. If teams can hot-swap prompts or tools in production without review, you don’t have a machine COO, you have distributed risk.
How Do You Safely Let AI Agents Manage Operational Work?
- Define decision rights, access limits, audit logs
- Require human approval for high-impact actions
- Measure error rate, escalations, rollback frequency
Build The Machine COO You Can Defend In An Ops Review
Machine leadership pays off when you convert ambition into enforceable boundaries: clear authority, tight access, measurable service levels, and a human chain of command. You protect the organization by forcing decisions into policies and thresholds the machine can execute consistently. You scale by treating the system like production software, with releases, monitoring, rollback, and incident drills. You keep trust by publishing what the machine uses, what it ignores, and how a human can override it. If you run it that way, the machine doesn’t replace your COO, it gives you COO-grade control over work that used to slip through the cracks.

Jay Holstine is a Vistage Chair and veteran tech CEO with 20+ years of experience in SaaS and operations. The founder of SigmaFlow and former CEO of Freightflow, he now leads a Dallas–Fort Worth CEO peer group and advises executives on strategy, process improvement, and scalable growth.